Enterprise Streaming Lakehouse Platform
Realfuture
From data ingestion to lakehouse development and operations.
Built on Apache StreamPark and Apache Flink, Realfuture connects data ingestion, catalog management, SQL and application development, and production operations. Reuse data definitions, validate processing logic, publish jobs and maintain lakehouse tables within a shared workflow.
01 / Catalog & metadata
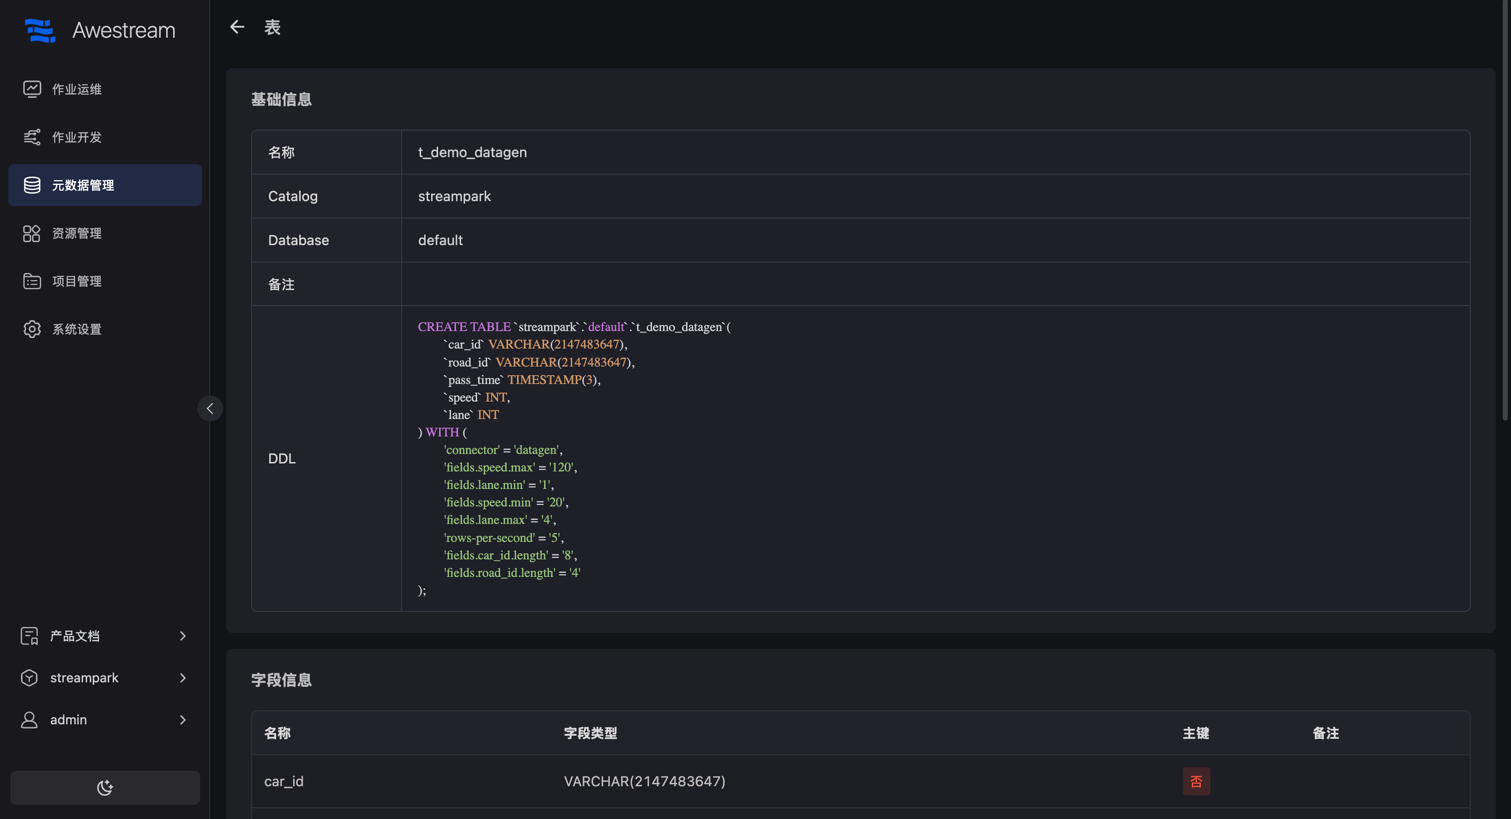
Reuse the data definitions your team works with.
Browse databases, streams and lakehouse tables through built-in and external catalogs. Manage supported objects with forms or SQL, and reuse metadata in authoring, validation and exploration.
- Discover tables and inspect columns, types and DDL.
- Filter Kafka topics and infer schemas from supported message formats.
- Manage tables, views and functions within a workspace.
02 / Development & validation
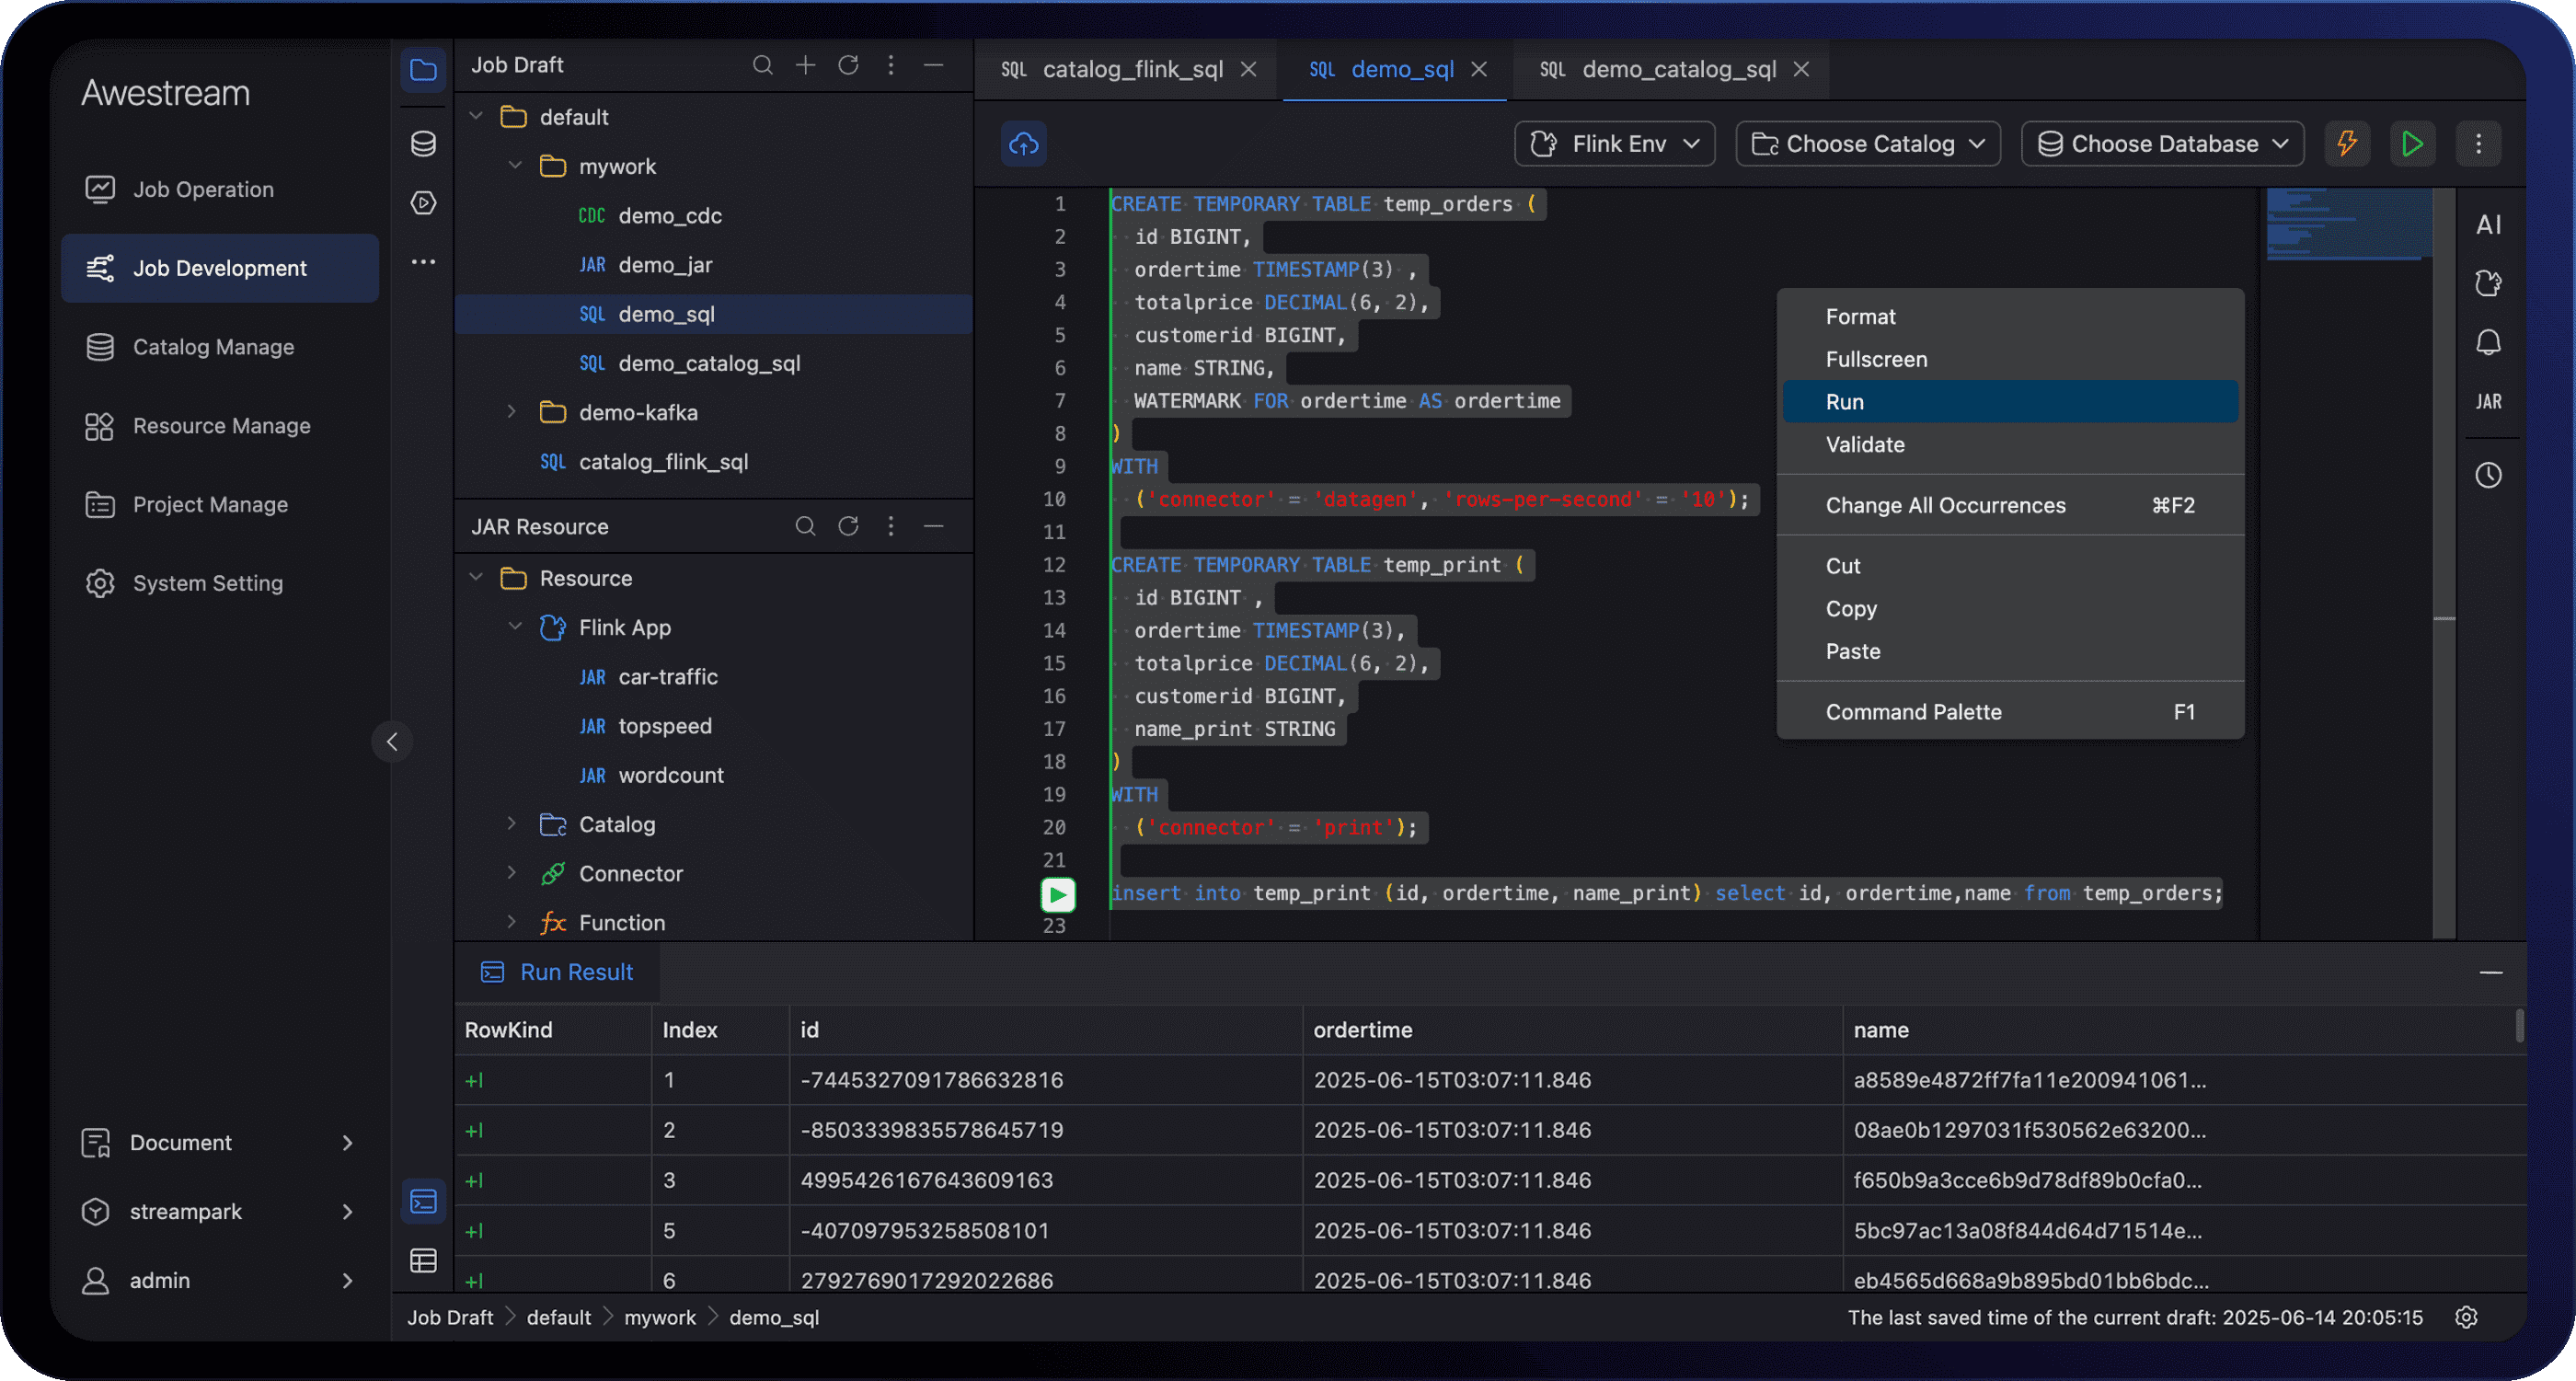
Choose the workflow that fits the job.
Write Flink SQL, configure CDC and visual ETL, or bring existing JARs and Git builds. Use catalog context, SQL completion, validation and result previews while developing.
- Use SQL for transformations, joins and aggregations.
- Configure ETL field mappings, filters and joins; inspect the generated SQL.
- Query supported databases through Native SQL to inspect source or target data.
03 / Data integration & lakehouse
Connect ingestion, processing and table maintenance.
Develop CDC pipelines with source and sink connectors, then use catalogs and Flink SQL to work with the data. Paimon integrations provide a foundation for lakehouse development and maintenance tasks.
- Define source tables, routing and transformations in CDC pipeline configuration.
- Use Paimon catalogs alongside database and messaging catalogs.
- Run adapted Paimon Actions for compaction, snapshots and branch or tag maintenance.
04 / Resources & publishing
Keep code, dependencies and releases connected.
Reuse connectors, formats, UDFs and application resources. Develop in drafts, review history and build from Git before publishing to a supported runtime target.
- Organize resources and configure the dependencies each job needs.
- Inspect Git references, build output, artifacts and changes.
- Manage draft history and publication separately from runtime recovery.
05 / Production operations
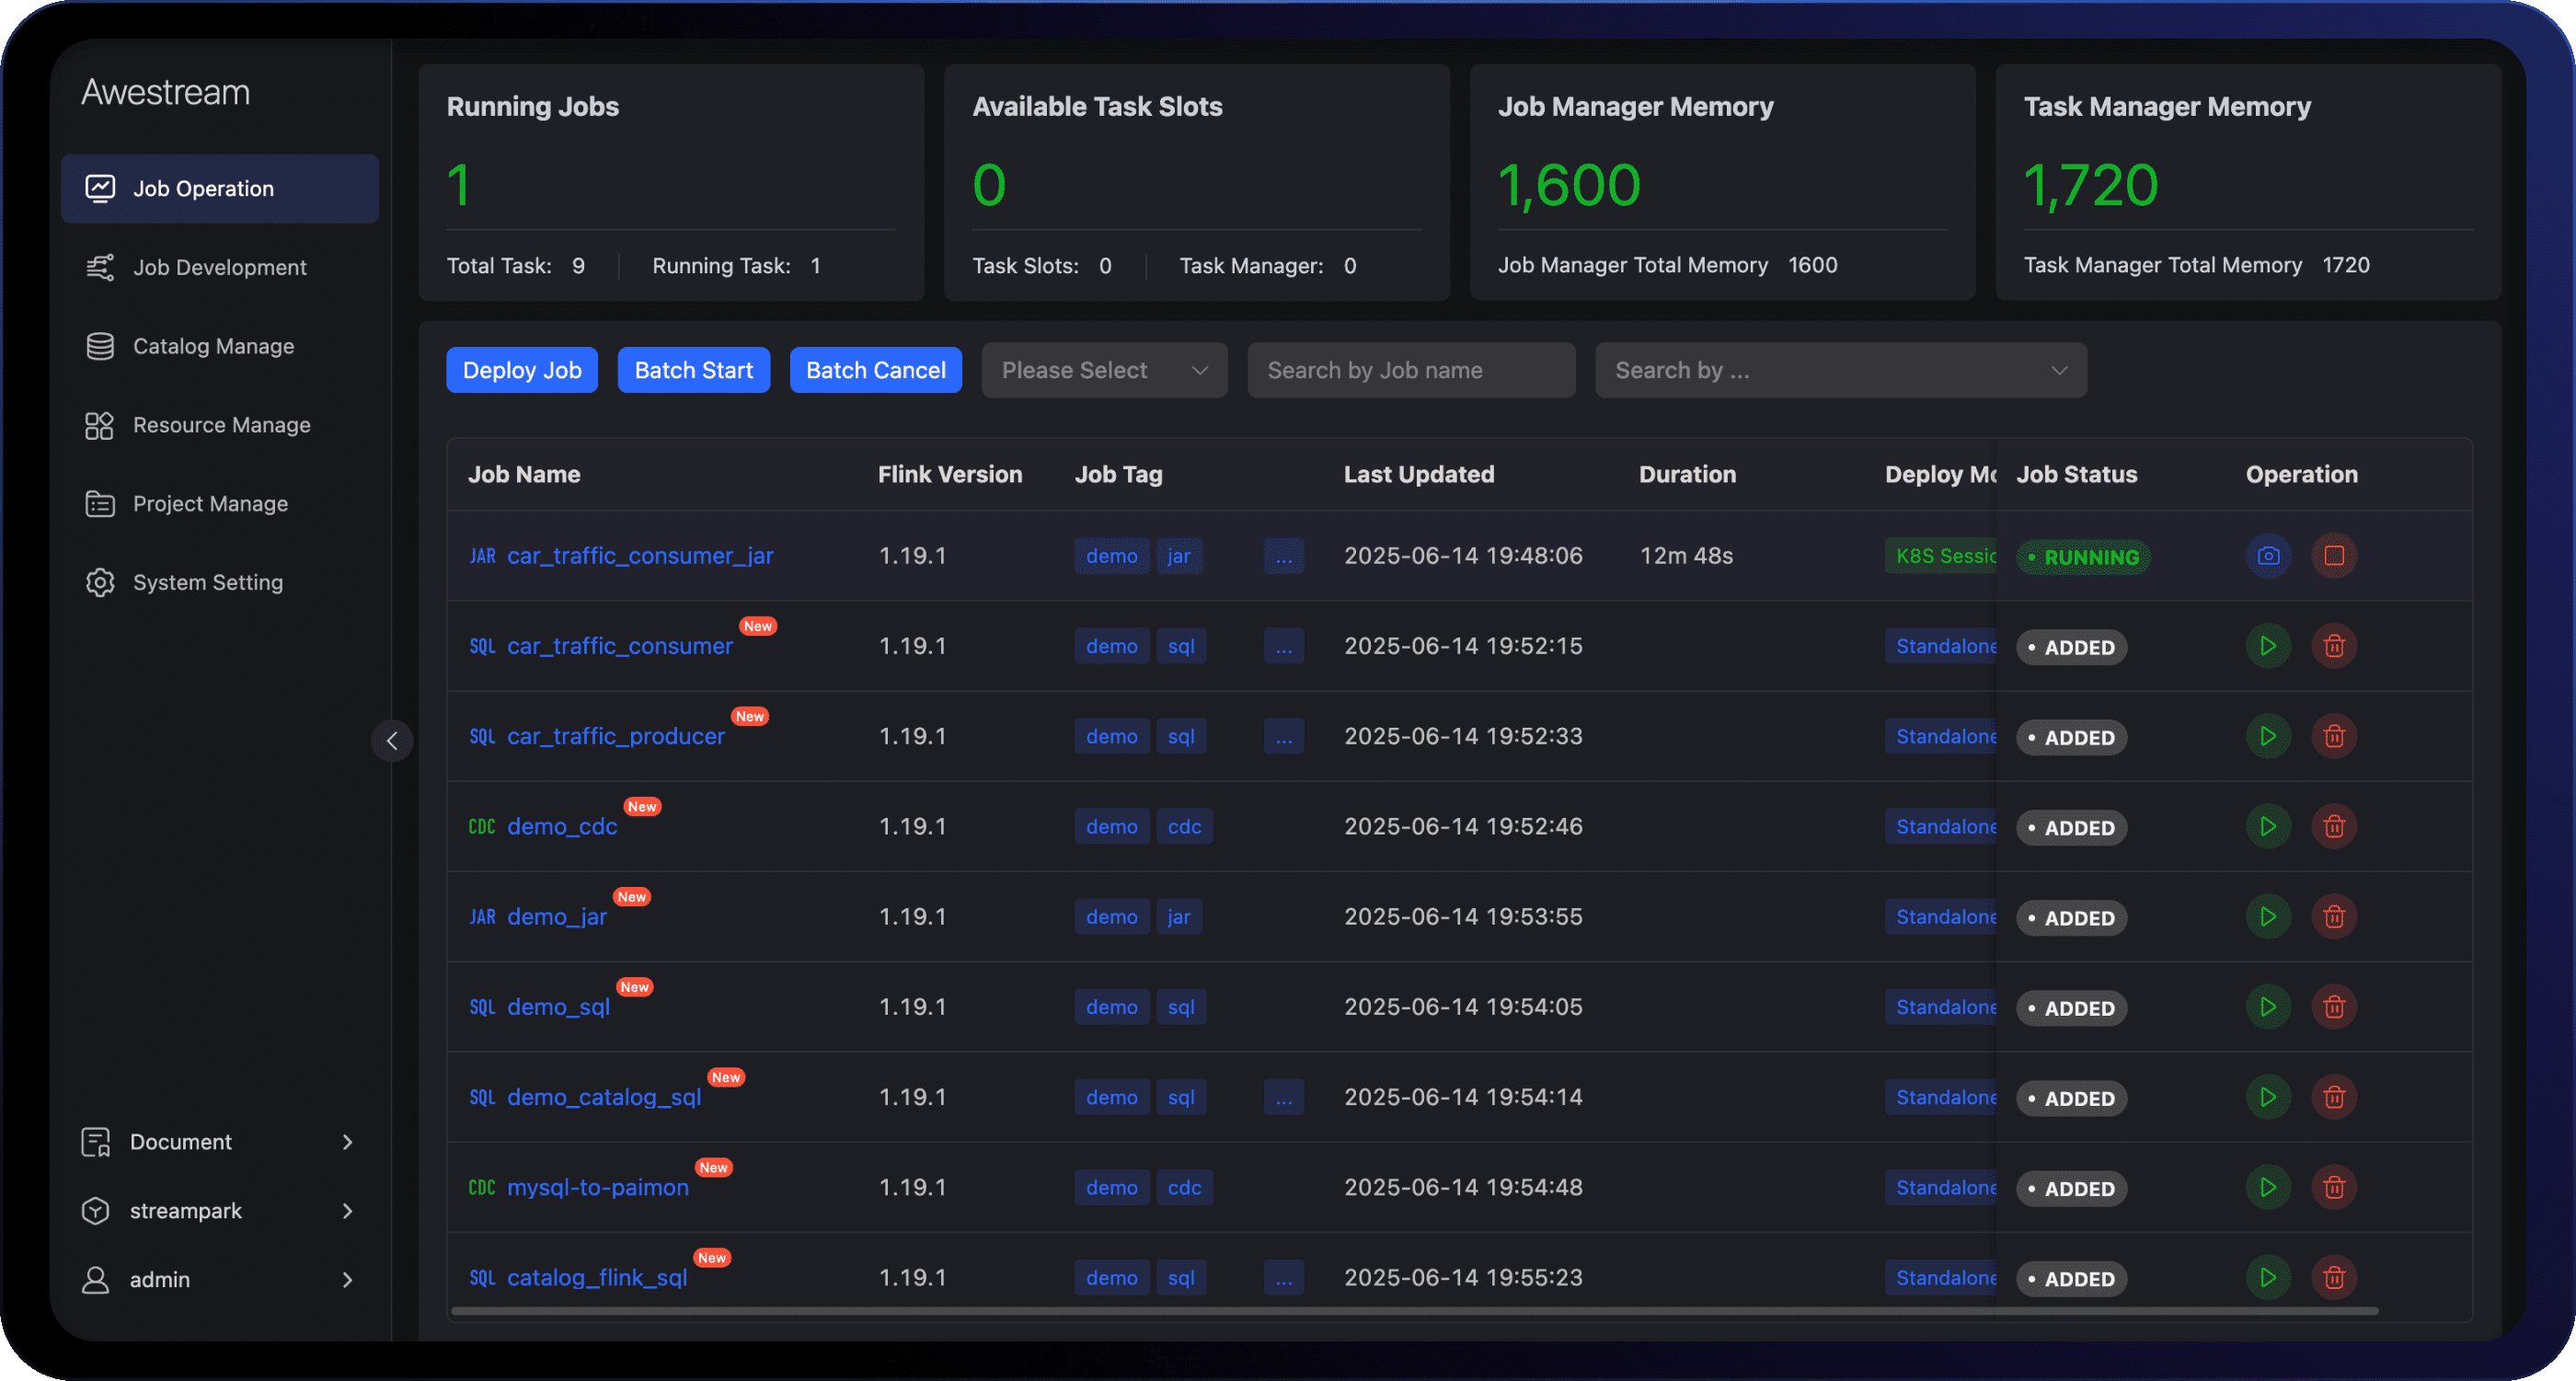
Investigate jobs with their runtime context.
Bring job status, metrics, logs, checkpoints and history together across connected runtimes. Workspace controls, audit records and recovery operations support the daily work of platform teams.
- Manage supported standalone, YARN and Kubernetes execution environments.
- Reconcile job state after platform startup and investigate lost connections.
- Use optional AI assistance for SQL or CDC generation, error explanations and job diagnosis.
Enterprise engineering
Software maintained for the work behind your data.
Realfuture develops and maintains enhancements across the platform, catalogs, Flink, Flink CDC and connectors. Enterprise services cover deployment, migration, troubleshooting and maintenance within the agreed software scope.
Catalog operations, query engines and connectors each have their own capabilities. Supported combinations, runtime requirements and optional services are documented for the selected release.